Gemini 4 Hydrogen Benchmarks, Fully Counted: The Official Table, AA 51/54, and an 8% Hallucination Rate
One day after launch, Hydrogen already has plenty of scores: Google's official table, Artificial Analysis's independent measurement, and specialist leaderboards from Vals and Agent Arena. But the scores come from different testers with different methodologies, and read together they argue with each other. This article lists every verifiable score and explains who measured each one, against whom, and how much to trust it.
Google's official table: three wins, two losses
| Test | Hydrogen | Sonnet 5.5 | GPT-6.1 Terra |
|---|---|---|---|
| SWE-sweep | 13.5% | 3.1% | 5.8% |
| Terminal-Bench 4.1 (cheating-adjusted) | 57.0% | 63.9% | — |
| Agents' Last Exam v1.1 | 71.6% | 60.4% | 69.8% |
| AutomationBench-AA | 76.1% | 71.8% | 60.2% |
SWE-sweep is the widest lead: 13.5% against Sonnet 5.5's 3.1% and Terra's 5.8%. But Terminal-Bench 4.1 is the item Hydrogen loses in the official table: 57.0% against Sonnet 5.5's 63.9%. Google picked the comparison models and test versions for this table — the fact that it includes a losing item suggests the table isn't cherry-picked to show wins only.
Other official scores: OSWorld-2.1 77.6% (Sonnet 5.5: 83.9%, another loss); HLE-Diamond 58.8% (Google calls it "class-leading" without naming the class); Terminal-Bench-Science 0.1 51.4%; Vals Tax Agent Bench 52.3% (#1 of 85); Vals Legal Research Bench 55.8% (tied #1); Multimodal Knowledge Agent (MKA) 53.4% (class-leading); Agent Arena #5. Against 3.8 Flash: Terminal-Bench 4.1 rises from 18.2% to 57% (high level, Google averaged 5 attempts per task).
Independent AA measurement: 51/54 and an 8% hallucination rate
| Measurement | Hydrogen | Comparison |
|---|---|---|
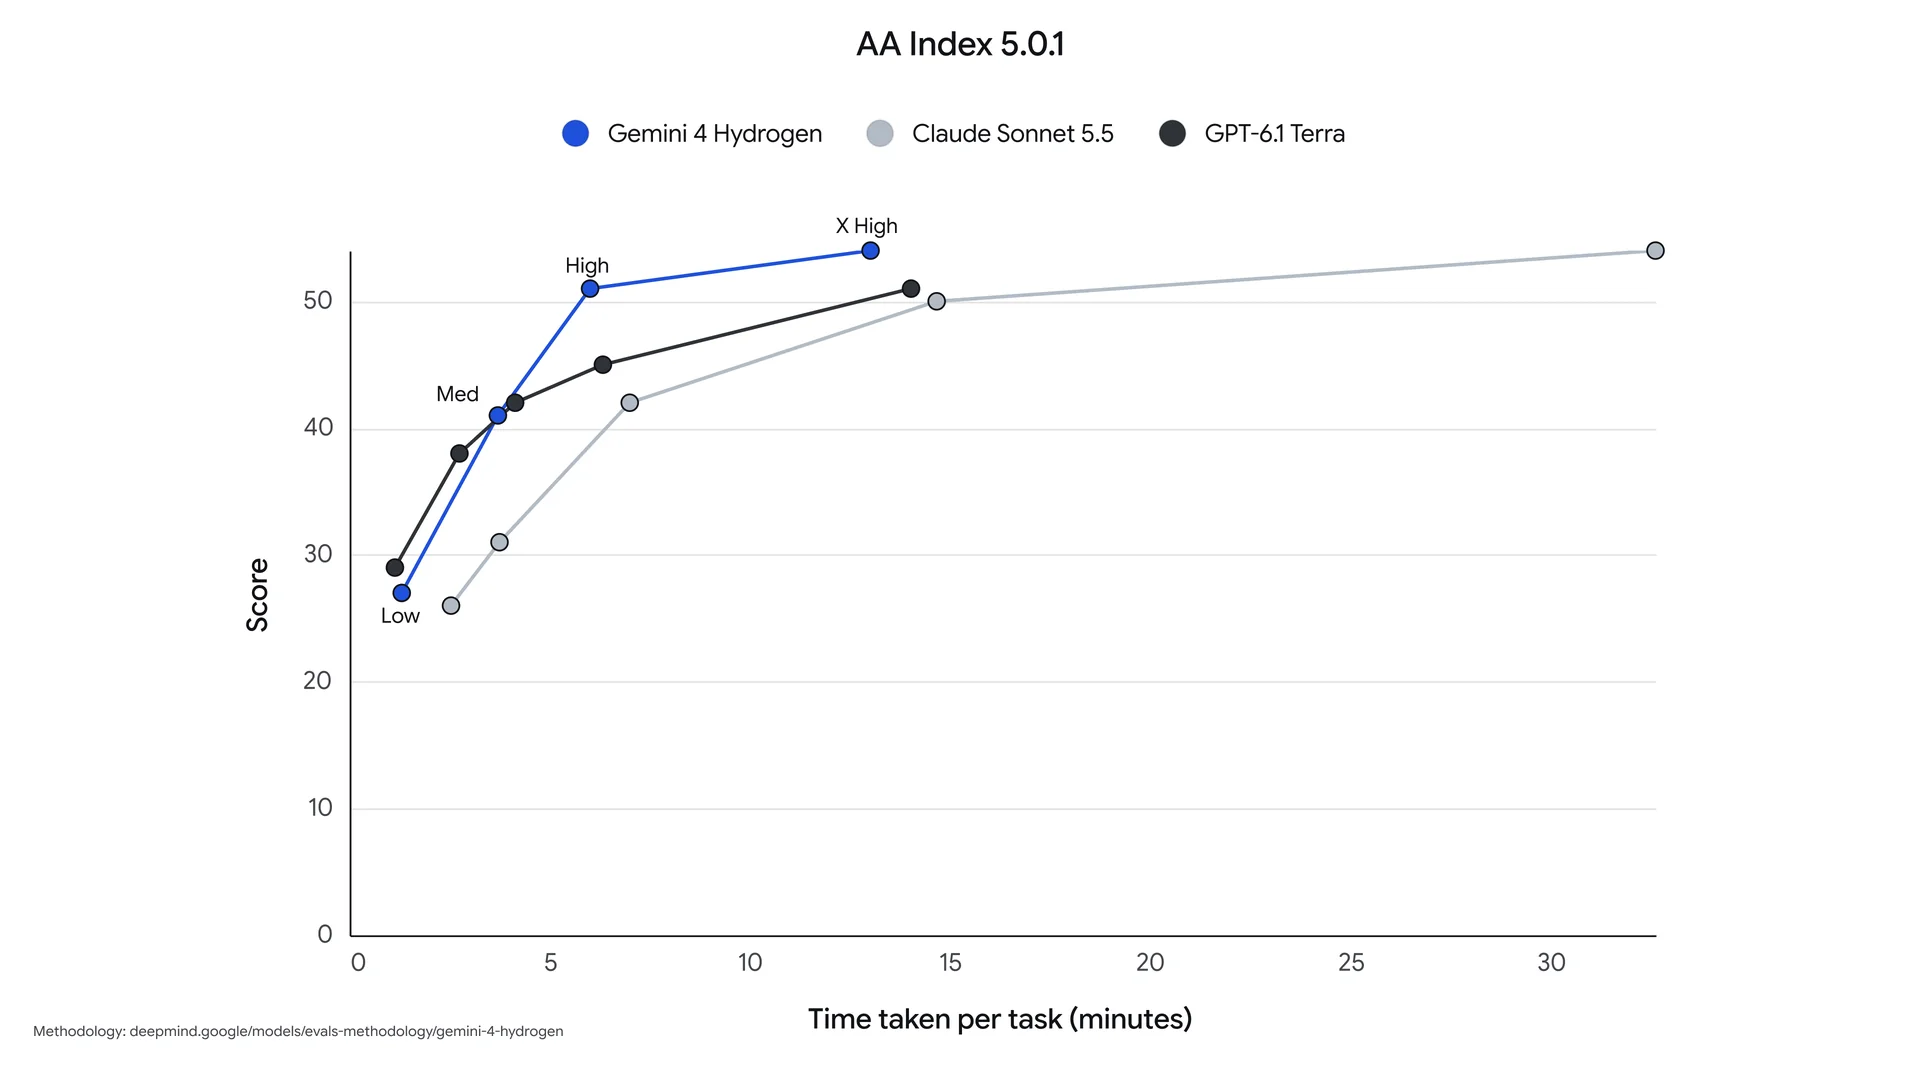
| AA Intelligence Index v5.0.1 (four levels) | low 27 / medium 41 / high 51 / xhigh 54 | Argon 50 (high); Sonnet 5.5 and Sol 55 each (max); Carbon 60 (high) |
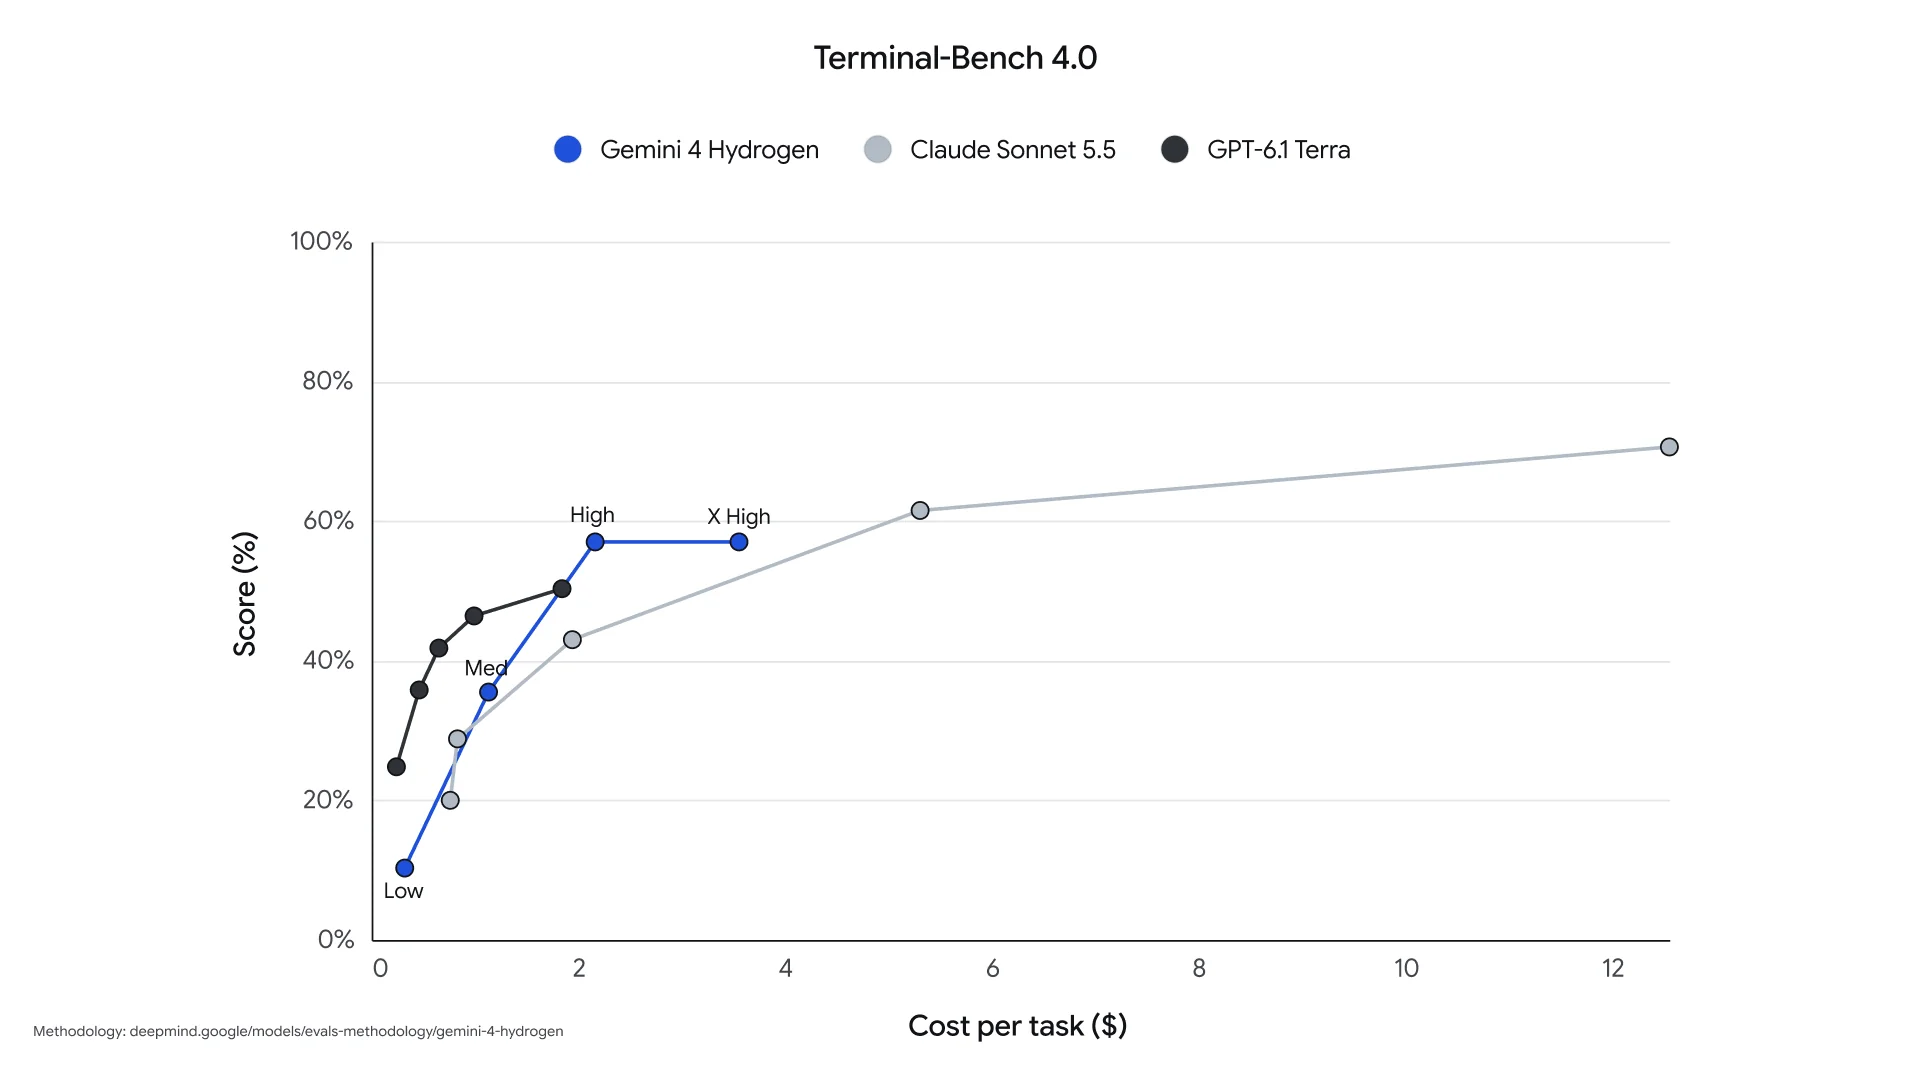
| Cost per task | low $0.29 / medium $0.80 / high $1.87 / xhigh $3.16 | xhigh ≈ 1/3 of Sonnet 5.5 (max), ≈ 2.5× Sol (max) |
| Time per task | high ~6.0 min; xhigh ~13–14 min | AA re-runs every 6 hours, so numbers drift |
| Time to first token (xhigh) | ~41 seconds | Peer median ~13.6s |
| Output speed (xhigh) | ~198 tokens/s | — |
| Total output tokens over the index run | 304M | Peer median 72.8M |
| AA-Omniscience hallucination rate | 8% | Sonnet 5.5 43%; GPT-6.1 Sol 52% |
| Terminal-Bench 4.0 (AA) | 54% (same at high and xhigh), 11th of 64 | Sol 56%; Sonnet 5.5 64% |
| Terminal-Bench-Science 0.1 (AA) | high 41% → xhigh 50% | Sonnet 5.5 53% (the-decoder) |
| AA-Briefcase / GDP.pdf | Presentation quality above other Gemini models (incl. Carbon); GDP.pdf tied highest at medium | — |
Artificial Analysis's measurement is more trustworthy: the tester is independent, the method is public, and it re-runs every 6 hours. But note: AA's numbers drift — different sources reading at different times report different per-task times (xhigh: winbuzzer 13.0 min, stackfutures 13.5 min, AA model page FAQ 13.7 min). This article uses approximations; check the AA model page for the current reading.
How to read these scores: six caveats
First, Google picked the official table's opponents and versions. The comparison models are only Sonnet 5.5 and Terra — not Fable 5.2 (the AA leader at 65); and "class-leading" never says which models make up the class.
Second, Terminal-Bench 4.0 and 4.1 are different versions. AA's 54% is 4.0; the official table's 57% is 4.1, with different opponents and methods — don't compare them in one sentence.
Third, Orchestrator's benchmark version still isn't reconciled. Google's main blog says Terminal-Bench 4.0, the Antigravity post says 4.1, and neither gives an actual success-rate number.
Fourth, the safety figures name no comparator. Overreach down 81%, under-service down 79%, Gray Swan resilience up 2.3× — cellcog notes none of these sentences says compared with what.
Fifth, the HLE-Diamond comparison score has a single source. Sonnet 5.5's 53.3% appears only in one video summary, so it is not included in the comparison table here.
Sixth, AA re-runs every 6 hours. The 41.11-second first token (Nov 12) and 40.55 seconds (Nov 13) are readings of the same metric at different times; high-level first-token data is not published separately by AA.
Related articles
Reference source: this article is an original rewrite produced by this site; facts and figures were checked against deepmind.google Gemini model page official comparison table and the Artificial Analysis model page (Nov 12–13, 2026)
← Back to the Gemini 4 Hydrogen topic page