Hy4 Benchmarks, All of Them: 34 Official Items, AA 35 and the Harness Traps
Hy4's benchmark data comes in two batches: Tencent's official set — a 12-item main chart plus a 34-item appendix, comprehensive data — and Artificial Analysis' independent measurement on Nov 5, index 35. Both batches are credible, but they use different harnesses, and mixing them produces wrong conclusions. This article lists every checkable score and flags each harness trap.
The official 12-item chart: first in none
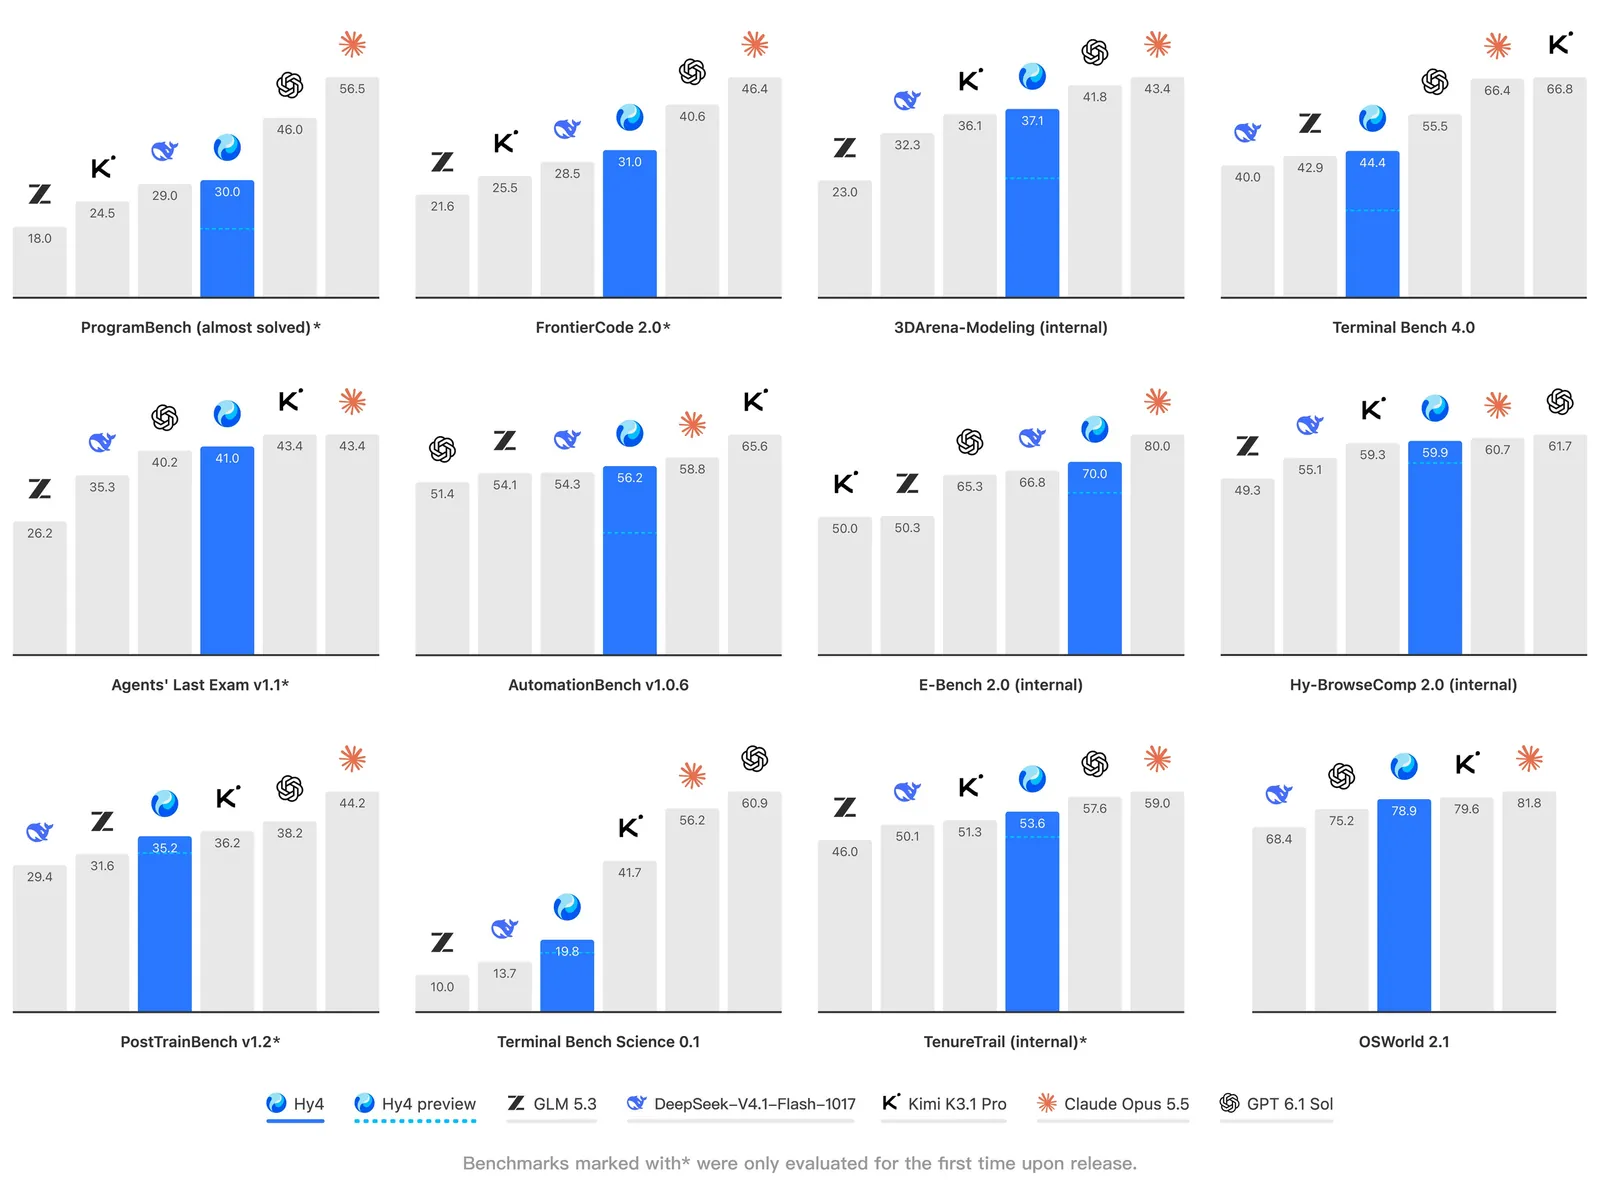
Tencent's news-release chart compares Hy4 with Hy4 preview, GLM 5.3, DeepSeek-V4.1-Flash-1017, Kimi K3.1 Pro, Claude Opus 5.5 and GPT-6.1 Sol, all re-run in the same harness. apiyi's rank-by-rank count: Hy4 is first in none of the 12, with its best result a second place on E-Bench 2.0 (70.0). It ties Kimi K3.1 Pro 6–6 among open models — Hy4 ahead in code generation, 3D modelling, retrieval and research tasks, Kimi ahead in terminal operation, automation and science-terminal tasks.
Closest to the closed flagships is OSWorld 2.1: 78.9%, just 2.9 points behind Claude Opus 5.5's 81.8% and ahead of GPT-6.1 Sol's 75.2%. Widest is Terminal-Bench 4.0: Kimi 66.8, Claude 66.4, GPT 55.5, Hy4 only 44.4; on ProgramBench, Claude 56.5, Hy4 30.0.
The official 34-item appendix: strengths and weaknesses are both clear
The launch-page appendix lists about 34 tests (reprinted in full by DataLearner), all measured at the highest reasoning tier at the time. Strengths cluster in agents and computer use: DeepSWE v1.1 74.9 (preview 64.3), APEX-Agents v1.1 75.2 (preview 53.9), OSWorld 2.1 78.9, MMMU-Pro 78.6, AutomationBench v1.0.6 56.2 (preview 36.3), HLE-Full (with tools) 59.1.
The weaknesses are equally clear, and Tencent didn't hide them: Hy-FrontierMath T5 (an internal math test) at just 13.0, against GPT-6.1 Sol's 97.5 and Claude's 91.3; Goal2Repo 23.2, Claude 74.0; Terminal-Bench-Science 19.8, GPT 60.9; BuddyVQA Atlas (no tools) 55.6, Claude 75.3. SWE-Marathon v1.1's 43.8 was measured with the time limit doubled — note the condition. Another roughly 15 internal evaluations (ZeroBench-main 55.4, PostTrainBench 35.2, TenureTrail 53.6 and others) cannot be reproduced externally and should be read as Tencent's own account.
Independent measurement: AA index 35, No. 2 in China
Artificial Analysis published its independent measurement on Nov 5: Intelligence Index v5.0.1 of 35, tying Grok 4.7 (xhigh) and one point behind Claude Haiku 5.5 (max, 36); No. 2 among Chinese labs behind Kimi K3.1 Pro (46), ahead of Qwen3.8 Max (45) and DeepSeek V4.1 Flash (32.6). AA's own wording: below average for its price tier (median 41).
AA's item-level measurements deserve a close read. FrontierCode 2.0 at 31% is the best among Chinese labs (DeepSeek 28%, Kimi 25%). HLE-Diamond 33%. Cost per task about $0.78, roughly one-tenth of the same-scoring Grok. But AA-Omniscience v1.1 gives 50% accuracy and an 89% hallucination rate — Kimi's is 37%. Accuracy and hallucination rate are separate measures; don't read 89% as "89% of answers are wrong," and AA offers no explanation. On Agent Arena Hy4 sits 13th for now (ranking preliminary); Tencent says No. 1 among open-source entries.
AA also recorded two engineering traits: Hy4 is "slower than average, very verbose" — 160M output tokens generated during the evaluation, roughly twice the median; on OpenRouter, P50 throughput is about 63 tok/s with P50 time to first token about 2.9s. Some of the cheap per-task cost is eaten by verbose output.
The harness trap: 44.4% and 37% are both right
Terminal-Bench 4.0 has two numbers; don't mix them: the official 44.4% (Claude Code harness, up to 500 rounds, up to 13 hours per task) and AA's 37% (AA's own harness). Different test conditions, both correct, not the same test. Likewise, Kimi K3.1 Pro's TB 4.0 is 66.8% in Tencent's table and 65.7% under another harness — cite the source when quoting.
One more number needs a warning: the 39.39% circulating in some aggregations has unclear benchmark attribution and harness, and is not used on this page as a TB 4.0 score. The 39.39% previously cited on this site's Inkling page also needs correction.
Finance and office: Tencent-organized evaluations
The FiT finance crowdsourced test was organized by Tencent: 213 experts (153 external), 579 tasks, 4-point scale — Hy4 3.04, best among open models, DeepSeek-V4.1-Flash-1017 2.97, Kimi and GLM 5.3 both 2.68. The IRAB evaluation (Xuntu Technology) shows a 12.03-point improvement over the preview. The WorkBuddy office evaluation averaged 83.18 with a 96.15% pass rate, No. 1 in China in 9 of 12 scenarios. The organizers or data sources of these evaluations are connected to Tencent; discount accordingly.
Reference: DataLearner — Tencent Hy4: Benchmarks, Pricing, API and Model Parameters (rewritten and organized by ModelBrief; facts per official sources and Artificial Analysis)