Tencent Hunyuan Hy4: The Topic Page
Tencent Hunyuan's latest-generation model, released November 4, 2026: a 770B-parameter mixture-of-experts with vision understanding and computer use for the first time, and a 1M-token context. Tencent says it "joins the ranks of the strongest open-source models for the first time" — but the full release's weights are still unpublished, its Artificial Analysis index of 35 puts it second in China, and the gap to the best closed models remains clear, as Tencent itself admits. This page collects the official specs, the ways to try it, pricing, and the first hands-on reviews in English and Chinese — with unverified claims clearly marked.
Order Hy4: China region — Order TokenHub to try Hy4 · Global — Order TokenHub to try Hy4
01Key facts
What is confirmed: an open-camp flagship built for real productivity work — but "open" is currently a promise, and the only downloadable weights are August's preview.
- Released
- 2026-11-04 (Tencent's official news release and the Hunyuan launch page; Artificial Analysis lists Nov 3, a UTC-date conversion)
- Developer
- Tencent Hunyuan, the large-model team of Tencent, China
- Architecture
- Sparse MoE; 770B total parameters, about 49B active per token (Tencent Cloud's techpedia states the Hy4 series uses "770B total, 49B active"; preview model card: 78 layers, 256 routed experts + 1 shared expert, top-8 routing)
- Context
- 1M tokens (OpenRouter lists 1,048,576); about 960K input on TokenHub; max output 64K (preview documentation; OpenRouter lists 65,536)
- Input / output
- Input: text, image. Output: text. Thinking mode on by default; the API returns a reasoning_content field (preview documentation)
- New capabilities
- First-time vision understanding (fine-grained image processing, complex chart analysis, mathematical visual reasoning) and computer use (command line + graphical interface; specialist training on Blender and CAD)
- Price
- TokenHub: ¥6 in / ¥18 out per 1M tokens, ¥0.3 cache hits; international $0.834 / $2.501 / $0.042; 50% off through Dec 31, 2026, 23:59 Beijing time
- Benchmarks
- Artificial Analysis index 35 (No. 2 in China, behind Kimi K3.1 Pro's 46); official Terminal-Bench 4.0 44.4% (AA measured 37%); OSWorld 2.1 78.9%; finance crowdsourced test 3.04, best among open models
- Weights
- Full-release weights not published (Tencent says "coming soon," no date; system card to follow); only Hy4 preview is downloadable (Apache 2.0, BF16 about 1.56TB, FP8 about 814GB)
- Access
- Tencent Cloud TokenHub (model ID
hy4), OpenRouter (tencent/hy4), Hermes, OpenCode; WorkBuddy/CodeBuddy, Yuanbao, ima, WeCom assistant Dayuan - Hy4 Flash
- A lighter version "coming soon," inheriting the vision and agent capabilities at much lower per-task cost; no specs, date or price
- Knowledge cutoff
- Not published by Tencent
02Timeline
Since rebuilding its infrastructure in February, Hunyuan has shipped a major version about every two months; Hy4 went from teaser to launch in six days — but the weights still haven't landed.
- 2026-02
Tencent rebuilds its AI infrastructure; Hunyuan settles into a rhythm of a major version about every two months, preview first, then the full release.
- 2026-08-28
Hy4 preview launches and open-sources: a 770B-parameter MoE, text-only, 1M context; weights on Hugging Face, ModelScope, GitCode and CNB the same day under Apache 2.0, plus an FP8 variant.
- 2026-10-29
At the Tencent Global Digital Ecosystem Summit, Hy4's imminent launch is previewed: stronger long-horizon and real-productivity work, vision understanding for the first time; Hy4 Flash teased alongside. WorkBuddy is said to have handled over 9 billion task requests since its March launch.
- 2026-11-04
Hy4 full release: vision + computer use for the first time, pretraining and post-training scaled up significantly; pricing unchanged from preview, 50% off on TokenHub through Dec 31; free WorkBuddy/CodeBuddy quota through Nov 15. Weights "coming soon," no date given.
- 2026-11-05
Artificial Analysis publishes its independent measurement: index 35, No. 2 in China. The same day Tencent expands Hy4's inference cluster tenfold — WorkBuddy users hit usage quotas on day one (Pandaily).
- 2026-11-06 – 11
GeekPark and InfoQ publish Chinese hands-on tests; English-language outlets verify the weights status: a Nov 11 re-check of Hugging Face still finds preview weights only, with
tencent/Hy4returning 401. - 2026-11-12
Woshipm publishes a Tongfu Inn hands-on test: a pelican video, a 67-box annotation with a numbering mix-up, a 30-minute Blender build; 82 credit records show video rendering took 98.6%.
- Future
Full-release weights and system card "in the coming days" (no date); Hy4 Flash coming soon (no specs); the next generation, Hy5, will be larger still (Tencent's statement).
03Official specs
As published by Tencent (news release, Hunyuan launch page, Tencent Cloud documentation and the OpenRouter listing, checked Nov 13, 2026). Note: the Nov 4 release post did not restate the full release's parameter count — 770B/49B comes from Tencent Cloud's techpedia and the preview model card, pending the system card.
- Status
- Released (2026-11-04); full-release weights pending
- Model ID
- hy4 (TokenHub); tencent/hy4 (OpenRouter)
- Architecture
- Sparse MoE; 770B total parameters, about 49B active per token
- Context window
- 1M tokens (OpenRouter lists 1,048,576); about 960K input on TokenHub
- Max output
- 64K tokens (preview documentation; OpenRouter lists 65,536)
- Input
- Text, image
- Output
- Text
- Reasoning
- On by default; API returns reasoning_content (preview documentation)
- API protocols
- Compatible with OpenAI Chat Completions, OpenAI Responses, Anthropic Messages (preview documentation)
- New capabilities
- Vision understanding; computer use (CLI + GUI; specialist training on Blender and CAD)
- Benchmarks
- AA index 35 (v5.0.1); Terminal-Bench 4.0 44.4% (official)
- Weights
- Full release not published; preview downloadable (Apache 2.0, BF16 about 1.56TB, FP8 about 814GB)
- License
- Full-release license unpublished; preview is Apache 2.0
- API price
- ¥6 in / ¥18 out per 1M tokens; 50% off through Dec 31, 2026
04How to try it: five routes
With the full-release weights still unpublished, every route is a hosted API or a Tencent product — there is no self-hosting path yet. Fastest starts: the WorkBuddy free quota and OpenRouter.
1Tencent Cloud TokenHub (official main route)
Tencent Cloud's model-calling platform, model ID hy4 (preview: hy4-preview). Same list price in Guangzhou and Singapore; 50% off through Dec 31, 2026, 23:59 Beijing time. OpenAI-compatible APIs; TokenHub also hosts third-party models for side-by-side comparison.
2OpenRouter (main route for international developers)
Model ID tencent/hy4, endpoint tencent/hy4-20261104; live price $0.417 / $1.2505 per 1M input/output tokens (marked as 50% off), cache reads $0.021. Context 1,048,576 tokens, max output 65,536 tokens; supports reasoning, tools/tool_choice and JSON-schema structured output. P50 throughput about 63 tok/s, P50 time to first token about 2.9s.
3WorkBuddy / CodeBuddy (free quota)
Tencent's agent office products with Hy4 built in. A free quota was offered Nov 4–15 (later extended to Nov 15, 23:59); users hit limits on day one, and Tencent expanded the inference cluster tenfold and raised the free quota — limits can still apply at peak times, and the official advice is to switch to Hy3 when that happens. Best for zero-code trials of long-horizon agents, two-way document editing and office collaboration.
4Yuanbao, ima and WeCom's Dayuan assistant
Tencent's consumer and office products have Hy4 integrated — no development needed, use it inside the product. QQ, Honor of Kings, Peacekeeper Elite, WeRead and Tencent News are still being integrated.
5Third-party platforms: Hermes, OpenCode
The API is also live on Hermes and OpenCode, useful for coding-agent workflows. A listing site also quoted Novita AI at $0.42 / $1.25 (checked Nov 12, not verified by this site).
05Pricing
List prices are identical to the preview — more capability, same price. The 50% discount ends Dec 31; budget on list prices after that. Prices checked Nov 10–13, 2026; the checkout page price is authoritative.
| Item (per 1M tokens) | List price | 50% off (through Dec 31, 2026) |
|---|---|---|
| TokenHub input (Guangzhou / Singapore) | ¥6.00 | ¥3.00 |
| TokenHub output | ¥18.00 | ¥9.00 |
| TokenHub cache-hit input | ¥0.30 | ¥0.15 |
| International input | $0.834 | $0.417 |
| International output | $2.501 | $1.2505 |
| International cache reads | $0.042 | $0.021 |
| OpenRouter (input / output / cache reads) | $0.834 / $2.501 / $0.042 | $0.417 / $1.2505 / $0.021 |
| WorkBuddy / CodeBuddy free quota | A free quota, Nov 4–15 | — |
Task cost: AA measured about $0.78 per task
Artificial Analysis' independent measurement gives about $0.78 per index task, roughly one-tenth of the same-scoring Grok 4.7 (xhigh) and one-thirteenth of Qwen3.8 Max (per Tencent's citation of the AA comparison). The cheapness is not in the unit price — $0.834/$2.501 is mid-pack for its tier — but in the task structure; the other side is output volume: Hy4 generated 160M output tokens in the AA evaluation, roughly twice the median, and verbosity eats part of the price advantage. OpenRouter reports a cache-hit rate of about 93%, so long-context tasks with repeated prefixes may bill below list price in practice.
Official pages: Tencent official news release · Hunyuan Hy4 launch page · Tencent Cloud Hy4 intro
Order Hy4: China region — Order TokenHub to try Hy4 · Global — Order TokenHub to try Hy4
06First hands-on reviews
All from the first wave, Nov 4–13: small samples and inconsistent methods, so treat each as a case study. Every entry carries a verdict badge; "Read on this site" opens our rewritten deep-dive article, with the original source at the end.
Chinese sources
GeekPark: CPO research report, 3D watch, game remake
Verdict: At the open-camp first-tier threshold; still chasing the global topSource: GeekPark, after 2026-11-04 (long-horizon agents, multimodal work and vision coding)
A CPO investment-research task delivered a report PDF plus a recalculable valuation model, described as a "junior research assistant" prototype; a Three.js 3D mechanical watch explainer page ran its full interaction loop; an NAIAD game remake completed the "watch frames → rebuild → render and self-check" loop. Conclusion: vision makes the product more useful, but does not decide the race; the real test is Hy5.
Read on this site → (original ModelBrief rewrite)
Tongfu Inn hands-on: pelican video, 67-box annotation, Blender build
Verdict: The eyes and hands work; spatial consistency and tabulated output still need human sign-offSource: Woshipm (Shuzhi Benliu), Nov 12, 2026 (WorkBuddy tests: video generation, visual annotation, Blender modelling)
A pelican video arrived in 13 minutes with the atmosphere right but the inn's layout changed and the back door missing; the hall annotation produced 67 numbered boxes and a 15-category table, but boxes 52/53 disagree with the table; a 30-minute Blender build got the beams, corridor and lattice windows, but turned a landing staircase straight and repeated one window pattern. Of 3,429.15 credits across 82 records, video rendering took 98.6%.
Read on this site → (original ModelBrief rewrite)
InfoQ: a tower-defense game in 55 minutes, three rounds
Verdict: The task-closure capability is a real change; details still need human sign-offSource: InfoQ, after 2026-11-04 (WorkBuddy tests: game development, visual reasoning, business planning, creative design)
A tower-defense game built from scratch in three rounds totalling 55 minutes (14m10s / 18m / 23m18s), from engineering setup to deployment with automated simulation and Chrome regression testing throughout; a dual-robot scheduling task passed all four dimensions and proved optimality; business-document reconciliation was accurate but included a counting error and an unfounded inference; a business-plan PPT showed better business judgment than Hy3, and poster design was more creative but less precise.
Caixin: Tencent admits a significant gap to the best closed models
Verdict: Rare candour in a launch statementSource: Caixin, 2026-11-04
The Hunyuan team calls Hy4 "currently one of the strongest open-source models" while admitting a significant gap to the best closed models, and says it will "steadily expand pretraining and post-training scale to narrow it." Since rebuilding its infrastructure in February, Hunyuan has iterated a major version about every two months; the next version, Hy5, will be larger still.
English sources
madrobot: can use a computer, still trails Claude
Verdict: Tencent's own chart exposes the gapSource: madrobot.blog, 2026-11-04
Tencent's launch post unusually devotes a whole section to its limitations: frontier math, long-horizon development, model iteration and VQA still lag the best closed models by "a significant gap." The official chart backs that up: Terminal-Bench 4.0, Hy4 44.4% against Claude Opus 5.5's 66.4% and GPT-6.1 Sol's 55.5%; closest on OSWorld 2.1 (78.9% vs Claude's 81.8%). Weights out of reach, license undecided.
Artificial Analysis independent measurement: 35, No. 2 in China
Verdict: Outstanding value, hallucination rate is the weak spotSource: Artificial Analysis, 2026-11-05 (index v5.0.1)
AA index 35, tying Grok 4.7 (xhigh), No. 2 among Chinese labs (Kimi K3.1 Pro 46 first); about $0.78 per task, roughly one-tenth of the same-scoring Grok. But AA-Omniscience gives an 89% hallucination rate (Kimi 37%), AA measured Terminal-Bench 4.0 at only 37% (official 44.4%), and Hy4 was "slower than average, very verbose."
Read on this site → (original ModelBrief rewrite)
apiyi: first in none of the 12 benchmarks
Verdict: Don't be carried away by "strongest open source"Source: apiyi, 2026-11-04 (rank-by-rank analysis of the official 12-benchmark chart)
Counting the official chart rank by rank: Hy4 is first in none of the 12, with its best result a second place on E-Bench 2.0; it ties Kimi K3.1 Pro 6–6 among open models; the appendix is harsher — Hy-FrontierMath T5 at just 13.0 against GPT-6.1 Sol's 97.5. Caveat: all numbers are Tencent's own measurements, with rivals re-run by Tencent rather than their published values.
Read on this site → (original ModelBrief rewrite)
Weights status check: a promise, not a state
Verdict: Only the preview is downloadableSource: digitalapplied, OrcaRouter, EveryInfra, 2026-11-05/07/11
Three independent checks agree: as of the Nov 11 re-check, Hugging Face still hosts only Hy4 preview weights; tencent/Hy4 returns 401, and there is no Hy4 repository on GitHub; the full release's parameter count, license and model card are unpublished. OrcaRouter's verdict: "the version number went up, the openness came down" — the preview open-sourced on launch day; the full release ships API-first, weights later.
Read on this site → (original ModelBrief rewrite)
06BArticles: our deep dives
The seven articles below are original ModelBrief rewrites and reorganization — restructured with added conclusions and buying advice, with facts and numbers checked against the original reviews. Read them on this site; each ends with its original source.
06CBenchmarks: official table + independent index
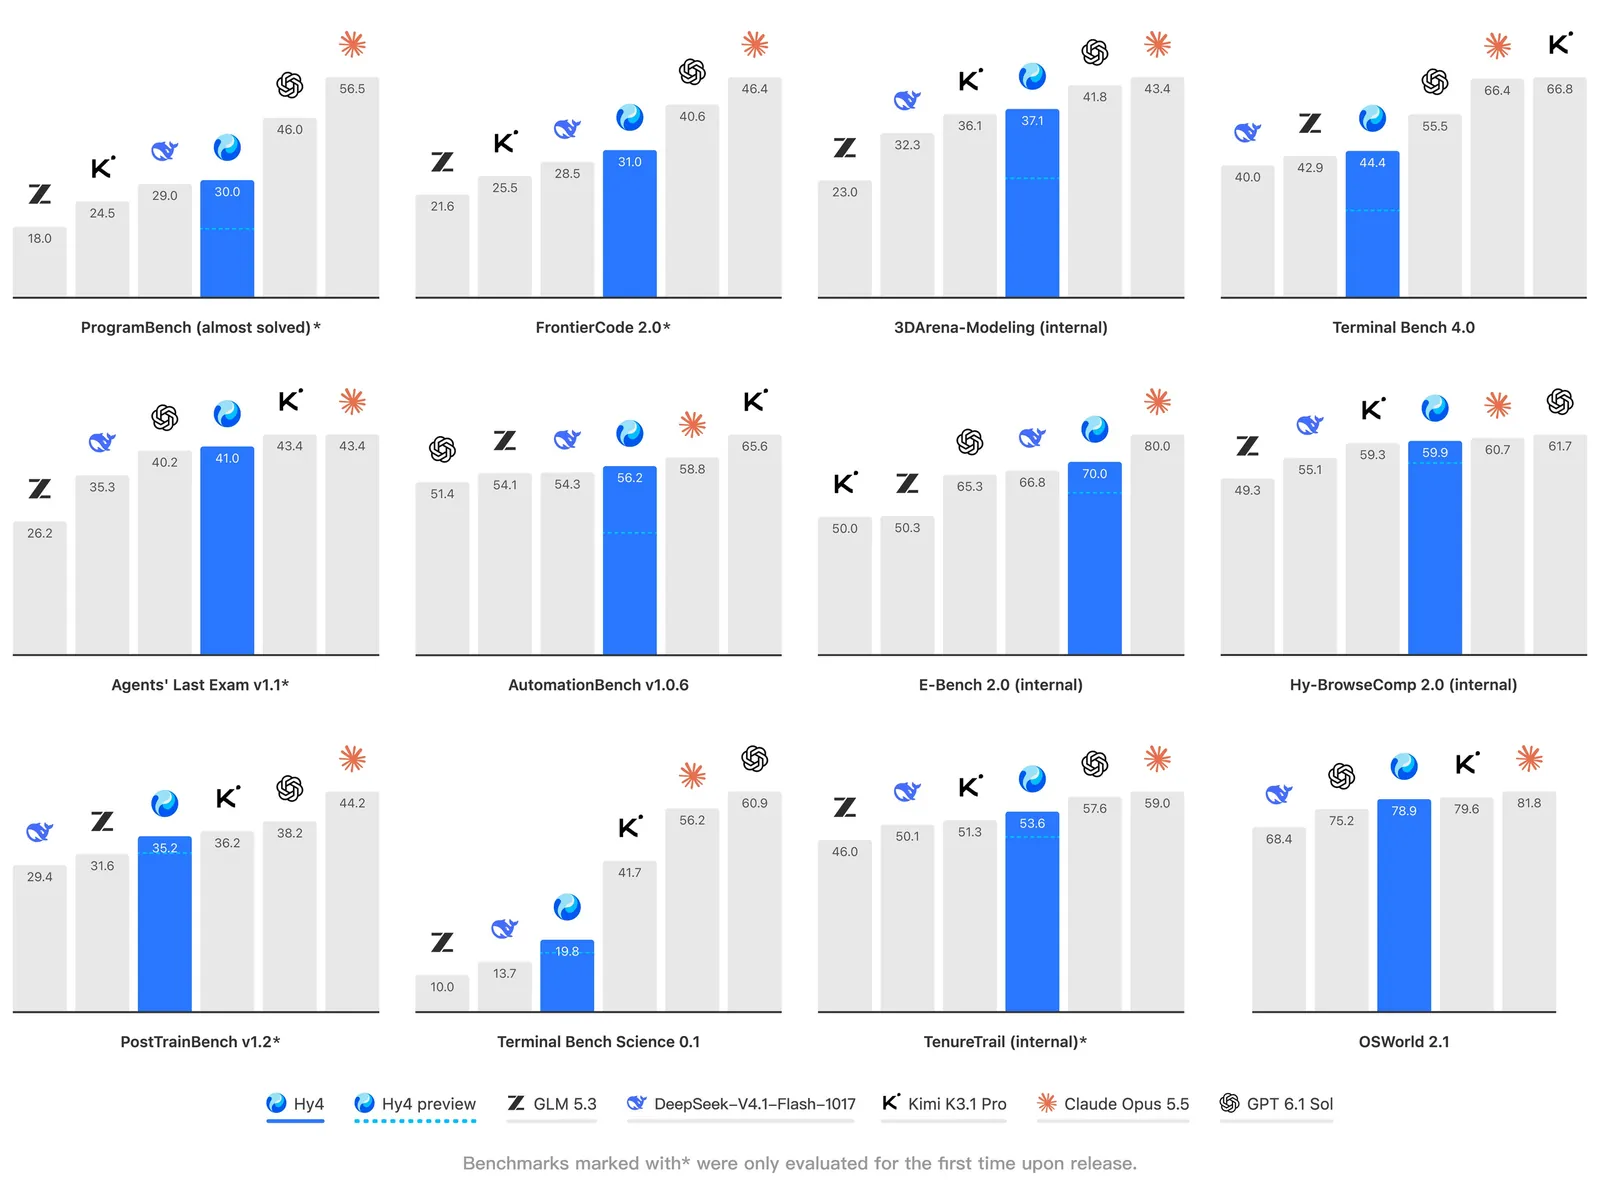
Tencent published a 34-item appendix and a 12-item main chart — comprehensive data, but all vendor-measured, with rival scores re-run by Tencent rather than each vendor's published values. Check the conditions before the scores, then see what independent measurement says.
| Test (official appendix, vendor-measured) | Hy4 | Hy4 preview | Comparison |
|---|---|---|---|
| DeepSWE v1.1 | 74.9 | 64.3 | — |
| APEX-Agents v1.1 (pass@1) | 75.2 | 53.9 | — |
| OSWorld 2.1 (partial score) | 78.9 | — | Claude Opus 5.5 81.8; Kimi K3.1 Pro 79.6; GPT-6.1 Sol 75.2 |
| MMMU-Pro | 78.6 | — | — |
| AutomationBench v1.0.6 | 56.2 | 36.3 | Kimi K3.1 Pro 65.6; Claude Opus 5.5 58.8 |
| Terminal-Bench 4.0 | 44.4 | 26.3 | Kimi K3.1 Pro 66.8; Claude Opus 5.5 66.4; GPT-6.1 Sol 55.5 |
| SWE-Marathon v1.1 | 43.8 | 31.9 | Time limit doubled |
| Agents' Last Exam v1.1 | 41.0 | — | Kimi / Claude 43.4 |
| FrontierCode 2.0 | 31.0 | — | Claude Opus 5.5 46.4; GPT-6.1 Sol 40.6 |
| ProgramBench (almost solved) | 30.0 | 17.5 | Claude Opus 5.5 56.5; GPT-6.1 Sol 46.0 |
| HLE-Full (with tools) | 59.1 | 57.3 | — |
| Terminal-Bench-Science 0.1 | 19.8 | 16.2 | GPT-6.1 Sol 60.9; Claude Opus 5.5 56.2 |
| Hy-FrontierMath T5 (internal) | 13.0 | 7.8 | GPT-6.1 Sol 97.5; Claude Opus 5.5 91.3 |
| Goal2Repo (internal) | 23.2 | 18.1 | Claude Opus 5.5 74.0 |
| BuddyVQA Atlas (no tools, internal) | 55.6 | — | Claude Opus 5.5 75.3 |
Independent index and third-party measurements
| Measurement | Source | Hy4 result | Comparison |
|---|---|---|---|
| AA Intelligence Index v5.0.1 | Artificial Analysis, Nov 5 | 35, No. 2 in China | Kimi K3.1 Pro 46; Grok 4.7 (xhigh) 35; Haiku 5.5 (max) 36; Qwen3.8 Max 45 |
| AA Terminal-Bench 4.0 | Artificial Analysis (own harness) | 37% | Official 44.4% (Claude Code harness) — different harness |
| AA FrontierCode 2.0 | Artificial Analysis | 31% | Best among China labs; DeepSeek V4.1 Flash 28%; Kimi 25% |
| AA-Omniscience v1.1 | Artificial Analysis | Accuracy 50%, hallucination rate 89% | Kimi K3.1 Pro 37% hallucination; accuracy and hallucination are separate measures |
| AA HLE-Diamond | Artificial Analysis | 33% | — |
| AA cost per task | Artificial Analysis | About $0.78 / task | About 1/10 of the same-scoring Grok 4.7 |
| AA output token volume | Artificial Analysis | 160M in the evaluation | Median about 72.8M (about 2×), "very verbose" |
| Agent Arena | Agent Arena (ranking preliminary) | 13th | Tencent says No. 1 among open-source entries |
| Finance crowdsourced test (579 tasks, 4-pt scale) | Organized by Tencent FiT, 213 experts | 3.04, best among open models | DeepSeek-V4.1-Flash-1017 2.97; Kimi / GLM 5.3 both 2.68 |
Full tally: our benchmarks article →
07Comparisons
vs Hy4 preview (predecessor)
| Dimension | Hy4 | Hy4 preview |
|---|---|---|
| Released | 2026-11-04 | 2026-08-28 |
| Parameters | 770B total / 49B active (Tencent Cloud figure) | 770B total / 49B active (model card) |
| Vision understanding | Yes (first time) | No (text-only) |
| Computer use | Yes (first time) | No |
| Weights | Not published | Apache 2.0, published |
| Terminal-Bench 4.0 | 44.4 | 26.3 |
| DeepSWE v1.1 | 74.9 | 64.3 |
| APEX-Agents v1.1 | 75.2 | 53.9 |
| Hallucination rate (internal general test) | 7.2% | 12.95% |
| Price | ¥6 / ¥18 (same) | ¥6 / ¥18 |
The full release is stronger than the preview on every axis — but "open" runs the other way: the preview open-sourced on launch day, while the full release so far has only a promise. Anyone wanting to run locally can only use the preview, which has no vision and no computer use.
vs open-weight rivals (Nov 13, 2026 basis)
| Model | AA index | Terminal-Bench 4.0 | API price $/1M (in/out) | Weights |
|---|---|---|---|---|
| Tencent Hy4 | 35 | 44.4% (official) / 37% (AA) | 0.83 / 2.50 (50% off: 0.42 / 1.25) | Pending |
| Kimi K3.1 Pro | 46 | 66.8% (Tencent's table) | — | Published (Nov 4) |
| DeepSeek V4.1 Flash | 32.6 | 33.8% (AA) / 40.0% (Tencent's table) | — | Open weights |
| GLM-5.3 | — | 41.9% (AA) / 42.9% (Tencent's table) | — | Open weights |
| Inkling 2 Small | 31 | 13.1% | 0.30 / 1.00 | Apache 2.0, published |
| GLM-5.3-Flash | 27.8 | 32.8% | — | Open weights |
The gap to closed flagships, drawn by Tencent itself
In the official chart, the gap to Claude Opus 5.5 and GPT-6.1 Sol is widest on the hardest tests: Hy-FrontierMath T5 at just 13.0 (GPT 97.5, Claude 91.3), Goal2Repo 23.2 (Claude 74.0), Terminal-Bench-Science 19.8 (GPT 60.9). Closest is computer use: OSWorld 2.1 at 78.9%, only 2.9 points behind Claude's 81.8% and ahead of GPT's 75.2%. Tencent devotes a section of its launch page to admitting "a significant gap remains" in frontier math, long-horizon development, model iteration and high-difficulty visual Q&A.
08What's missing (as of Nov 13)
- Full-release weights and system card (Tencent says "in the coming days," no date; still unpublished at the Nov 11 re-check)
- Full-release license (the preview is Apache 2.0; the full release's license is unpublished)
- Official confirmation of the full release's parameter count and layer architecture (the release post did not restate them; system card pending)
- Hy4 Flash specs, date and price (only "coming soon" is known)
- Knowledge cutoff date (not published by Tencent)
- Independent local-run tests and benchmark reproductions after the weights release (none exist yet)
- Further analysis of AA-Omniscience's 89% hallucination rate (AA offers no explanation; the harness difference with Tencent's internal 7.2% remains to be clarified)
- Detailed TokenHub availability differences between the international and domestic regions
- English-language independent deep hands-on reviews (current English coverage is analysis pieces; no independent benchmark reproductions)
09Rumor check
Most confusion about Hy4 comes from preview/full-release mix-ups — several reports assign the preview's weights, parameters and license to the full release. Clarified one by one below.
Not true "Hy4 is already open source"
The full-release weights were unpublished as of Nov 13: a Nov 5 check found tencent/Hy4 returning 401 with no Hy4 repository on GitHub; a Nov 11 re-check of Hugging Face still found only preview weights. The only downloadable weights are the August 28 Hy4 preview (Apache 2.0). Several aggregators (byteiota, verticaltabs) list the preview weights as the full release's — that's the mix-up.
Not true "Terminal-Bench 4.0 is 39.39%"
39.39% appears in some aggregation benchmark lists, but its benchmark attribution and test harness are unclear; the official TB 4.0 is 44.4% (Claude Code harness) and AA's independent measurement is 37%. 39.39% cannot be cited as the TB 4.0 score — the 39.39% previously cited on this site's Inkling page also needs correction.
Partly true "The 770B parameters are officially announced for the full release"
The Nov 4 release post did not restate the full release's parameter count or layer architecture; 770B/49B comes from Tencent Cloud's techpedia (phrased as the "Hy4 series") and the preview model card. The figure is likely reliable, but strictly speaking the system card is needed for confirmation; the full-release license is likewise unpublished.
Partly true "Hy4 is the strongest open-source model"
Only true in specific framings: best among open models in the finance crowdsourced test (organized by Tencent) and No. 1 among open-source entries in Agent Arena (ranking preliminary). But Hy4 is first in none of the 12 official chart items, its AA index is No. 2 in China (Kimi K3.1 Pro 46 ahead), and the gap to closed flagships is clear. "Strongest" depends on what's being compared and who organized the test.
Partly true "Hy4's hallucination rate is only 7.2%"
7.2% is the result of Tencent's internal general test (preview: 12.95%); the search-optimized internal test is 5.45% (preview: 15.76%). But AA-Omniscience's independent measurement gives an 89% hallucination rate — a different test with a different harness, measuring a different kind of "hallucination." Read the internal and independent numbers together; don't cherry-pick the flattering one.
Clarified "Was it released Nov 3 or Nov 4?"
Officially Nov 4 Beijing time; Artificial Analysis lists Nov 3, a UTC-date conversion. Some Chinese aggregators write Oct 29 — that was the summit preview date, not the release date.
10FAQ
When was Hy4 released?
November 4, 2026 (Tencent's official news release and the Hunyuan launch page, Beijing time; AA lists Nov 3 in UTC). The predecessor, Hy4 preview, was released and open-sourced on August 28, 2026. See section 02 for the timeline.
Where can I download Hy4's weights?
The full-release weights were unpublished as of Nov 13 and cannot be downloaded. Only Hy4 preview is available: Hugging Face repository tencent/Hy4-preview (plus an FP8 variant), Apache 2.0, BF16 about 1.56TB and FP8 about 814GB; also on ModelScope, GitCode and CNB. Note the preview is a text-only model with no vision and no computer use. See our weights-status article.
Is Hy4 open source?
The current state is "promised open source": Tencent says the full-release weights are "coming soon" with a system card to follow, but as of Nov 13 there is no delivery and no date, and the full-release license is unpublished. The August preview is open-sourced under Apache 2.0. For now the full release is accessible only via API — Tencent Cloud TokenHub, OpenRouter and Tencent's own products.
What does Hy4 cost?
TokenHub list prices: ¥6 in / ¥18 out / ¥0.3 cache hits per 1M tokens, the same as the preview; international $0.834 / $2.501 / $0.042. A 50% discount runs through Dec 31, 2026, 23:59 Beijing time (¥3/¥9/¥0.15; OpenRouter $0.417/$1.2505/$0.021), with list prices resuming after. See our pricing guide.
How do I use Hy4? Which channels are available?
API: Tencent Cloud TokenHub (model ID hy4), OpenRouter (tencent/hy4), Hermes, OpenCode. In-product: WorkBuddy/CodeBuddy (free quota Nov 4–15), Yuanbao, ima, the WeCom assistant Dayuan. QQ, Honor of Kings, WeRead and other Tencent products are still being integrated. Local deployment currently means the preview weights only.
What does Hy4's AA index of 35 mean?
Artificial Analysis' Intelligence Index v5.0.1 score is 35, tying Grok 4.7 (xhigh) and one point behind Claude Haiku 5.5 (max, 36); No. 2 among Chinese labs behind Kimi K3.1 Pro (46), ahead of Qwen3.8 Max (45) and DeepSeek V4.1 Flash (32.6). AA describes it as below average for its price tier (median 41).
Is Hy4's Terminal-Bench 4.0 44.4% or 37%?
Both numbers are correct, but under different test conditions: 44.4% is Tencent's official appendix (Claude Code harness, up to 500 rounds, up to 13 hours per task); 37% is Artificial Analysis' independent measurement (AA's own harness). Don't mix them. The 39.39% circulating in some aggregations has an unclear source and is not used on this page.
What's the difference between Hy4 and Hy4 preview?
The full release significantly scales up pretraining and post-training, adds vision understanding and computer use for the first time, and improves instruction following, long-text understanding and long-horizon agents across the board; Terminal-Bench 4.0 rises from 26.3 to 44.4 and DeepSWE from 64.3 to 74.9. Pricing is identical. But the preview open-sourced on launch day while the full release's weights are still unpublished — the biggest contrast between the two.
How does Hy4 compare with Kimi K3.1 Pro?
On the official 12-item chart they tie 6–6: Hy4 leads in code generation, 3D modelling, retrieval and research tasks; Kimi leads in terminal operation, automation and science-terminal tasks, with Terminal-Bench 4.0 at 66.8% (Hy4 44.4%). On the AA index Kimi scores 46 against Hy4's 35; in the finance crowdsourced test Hy4 scores 3.04 against Kimi's 2.68. See our open-weight rivals comparison.
Does Hy4 support vision and computer use?
Yes, both for the first time in the Hy series. Vision: fine-grained image processing, complex chart analysis, mathematical visual reasoning (official demo: locating a roughly 2-metre rooftop component in a 2.8-billion-pixel aerial image). Computer use: command line + graphical interface combined, with specialist training on Blender, CAD and other professional software; OSWorld 2.1 at 78.9%, only 2.9 points behind Claude Opus 5.5's 81.8%.
What is Hy4 Flash? When is it coming?
A lighter version of Hy4, inheriting the vision and agent capabilities at much lower per-task cost, aimed at extreme value. Tencent only says "coming soon" — no specs, date or price, so don't treat it as a speed tier of the current Hy4.
How large is Hy4's context window?
1M tokens (OpenRouter lists 1,048,576); about 960K input on TokenHub. Max output 64K tokens (preview documentation; OpenRouter lists 65,536).
11Sources
Every fact on this page comes from the public sources below (checked Nov 13, 2026).
Official
- Tencent — Tencent Launches Hy4, Joining the Ranks of the World's Leading Open-Source AI Models (official news release, with the 12-benchmark chart) Nov 4
- Tencent Hunyuan — Hy4 official launch page (with the 34-item benchmark appendix) Nov 4
- Tencent Cloud Developer Community — Hunyuan Hy4: Advantages and Application Scenarios
- Artificial Analysis — Tencent Hy4 model page (index 35) Nov 5
- DataLearner — Tencent Hy4: Benchmarks, Pricing, API and Model Parameters (34-item appendix reprint) Updated Nov 10
English reporting and analysis
- madrobot — Tencent Hy4 is out: it can use a computer but still trails Claude Nov 4
- apiyi — How Powerful Is Hy4? (rank-by-rank analysis of the 12 benchmarks) Nov 4
- digitalapplied — Tencent Hy4 Is Out: What Is Confirmed and What Is Not Yet Nov 4
- OrcaRouter — Tencent Hy4 vs Hy4 Preview: Newer Model, Less Open Nov 7
- CellCog — Tencent Hy4: Out of Preview, Now With Vision
- dev.to — Tencent's Hy4 Can See and Use Your Computer — Explained Honestly
- AI Affairs — Tencent expands Hy4 inference capacity tenfold after WorkBuddy users hit quotas Nov 5
- AICoder — Artificial Analysis: Tencent Hy4 Scores 35 on Intelligence Index v5 Nov 5
- EveryInfra — Tencent Hy4 function calling (Nov 11 Hugging Face weights re-check)
- AlphaSignal — Tencent's Hy4 Brings 1M Context and Agent Tools at a Tenth the Cost Nov 5
- TeamoRouter — Tencent Hy4 API: Price, Specs and How to Call
Chinese reporting and hands-on
- GeekPark — Hands-on with HY4: how far is Tencent's most solid model from the front line? (Chinese)
- InfoQ — Hy4 hands-on: how much of Tencent's product DNA did the model inherit? (Chinese)
- Woshipm — How Did Tencent Hunyuan Hy4 Do Working at Tongfu Inn? (pelican video, 67-box annotation, Blender build) Nov 12
- Caixin — Tencent releases Hunyuan Hy4, introducing vision understanding for the first time (Chinese) Nov 4
- Tencent Cloud Developer Community — Hunyuan Hy4 full release: can see images, can operate a computer (Chinese)