LongCat 2.5: The Topic Page
Meituan LongCat's latest-generation model, GA on November 2, 2026: a 1.6T-parameter mixture-of-experts with about 48B active per token, native multimodality (text, image and video input), trained for long-horizon agent work, with a 1M-token context. Its limited-time price of $0.30/$1.20 matches DeepSeek V4.1 Flash exactly, and Meituan self-reports 88.4 on Terminal-Bench 2.1 — but as of November 13 no independent lab has scored it, the discount has neither an end date nor a list price, and the weights quietly went MIT open-source on November 4, a change most early coverage hasn't caught up with. This page collects the official specs, the ways to try it, pricing, and the first hands-on reviews in English and Chinese — with unverified claims clearly marked.
01Key facts
What is confirmed: a 1.6T-parameter native multimodal agent model, priced head-to-head against DeepSeek V4.1 Flash, with MIT-licensed weights already out — but every eye-catching score is vendor-reported, with no independent verification at all.
- Released
- 2026-11-02 GA (live on the LongCat API Platform; tech blog announced it Nov 1, preview Sep 25). This site uses Nov 2 as the release date: the first day it was actually usable.
- Developer
- Meituan LongCat team, the large-model team of Meituan, China
- Architecture
- Sparse MoE; 1.6T total parameters, about 48B active per token (weights repo config.json: 38 layers, 768 routed experts, top-12 routing, MLA attention, 163,840-token vocabulary)
- Context
- 1M tokens (API figure 1,048,576, input + output combined); config base 524,288, extended via YaRN; max output 128K (documentation disagrees — see section 09)
- Input / output
- Input: text, image, video. Output: text. Reasoning returns via a reasoning_content field; temperature is fixed (1.0 with thinking on, 0.7 with it off — other values are silently overridden)
- New capabilities
- Native multimodal vision (multi-level discrete tokens, no separate vision encoder); video understanding added at GA; long-horizon agent training (F2P/P2P reinforcement learning, MOPD multi-teacher distillation)
- Price
- Limited-time discount: $0.30 in / $0.006 cached / $1.20 out per 1M tokens (¥2 / ¥0.04 / ¥8); no end date, no list price — Meituan says "prices may change"
- Benchmarks
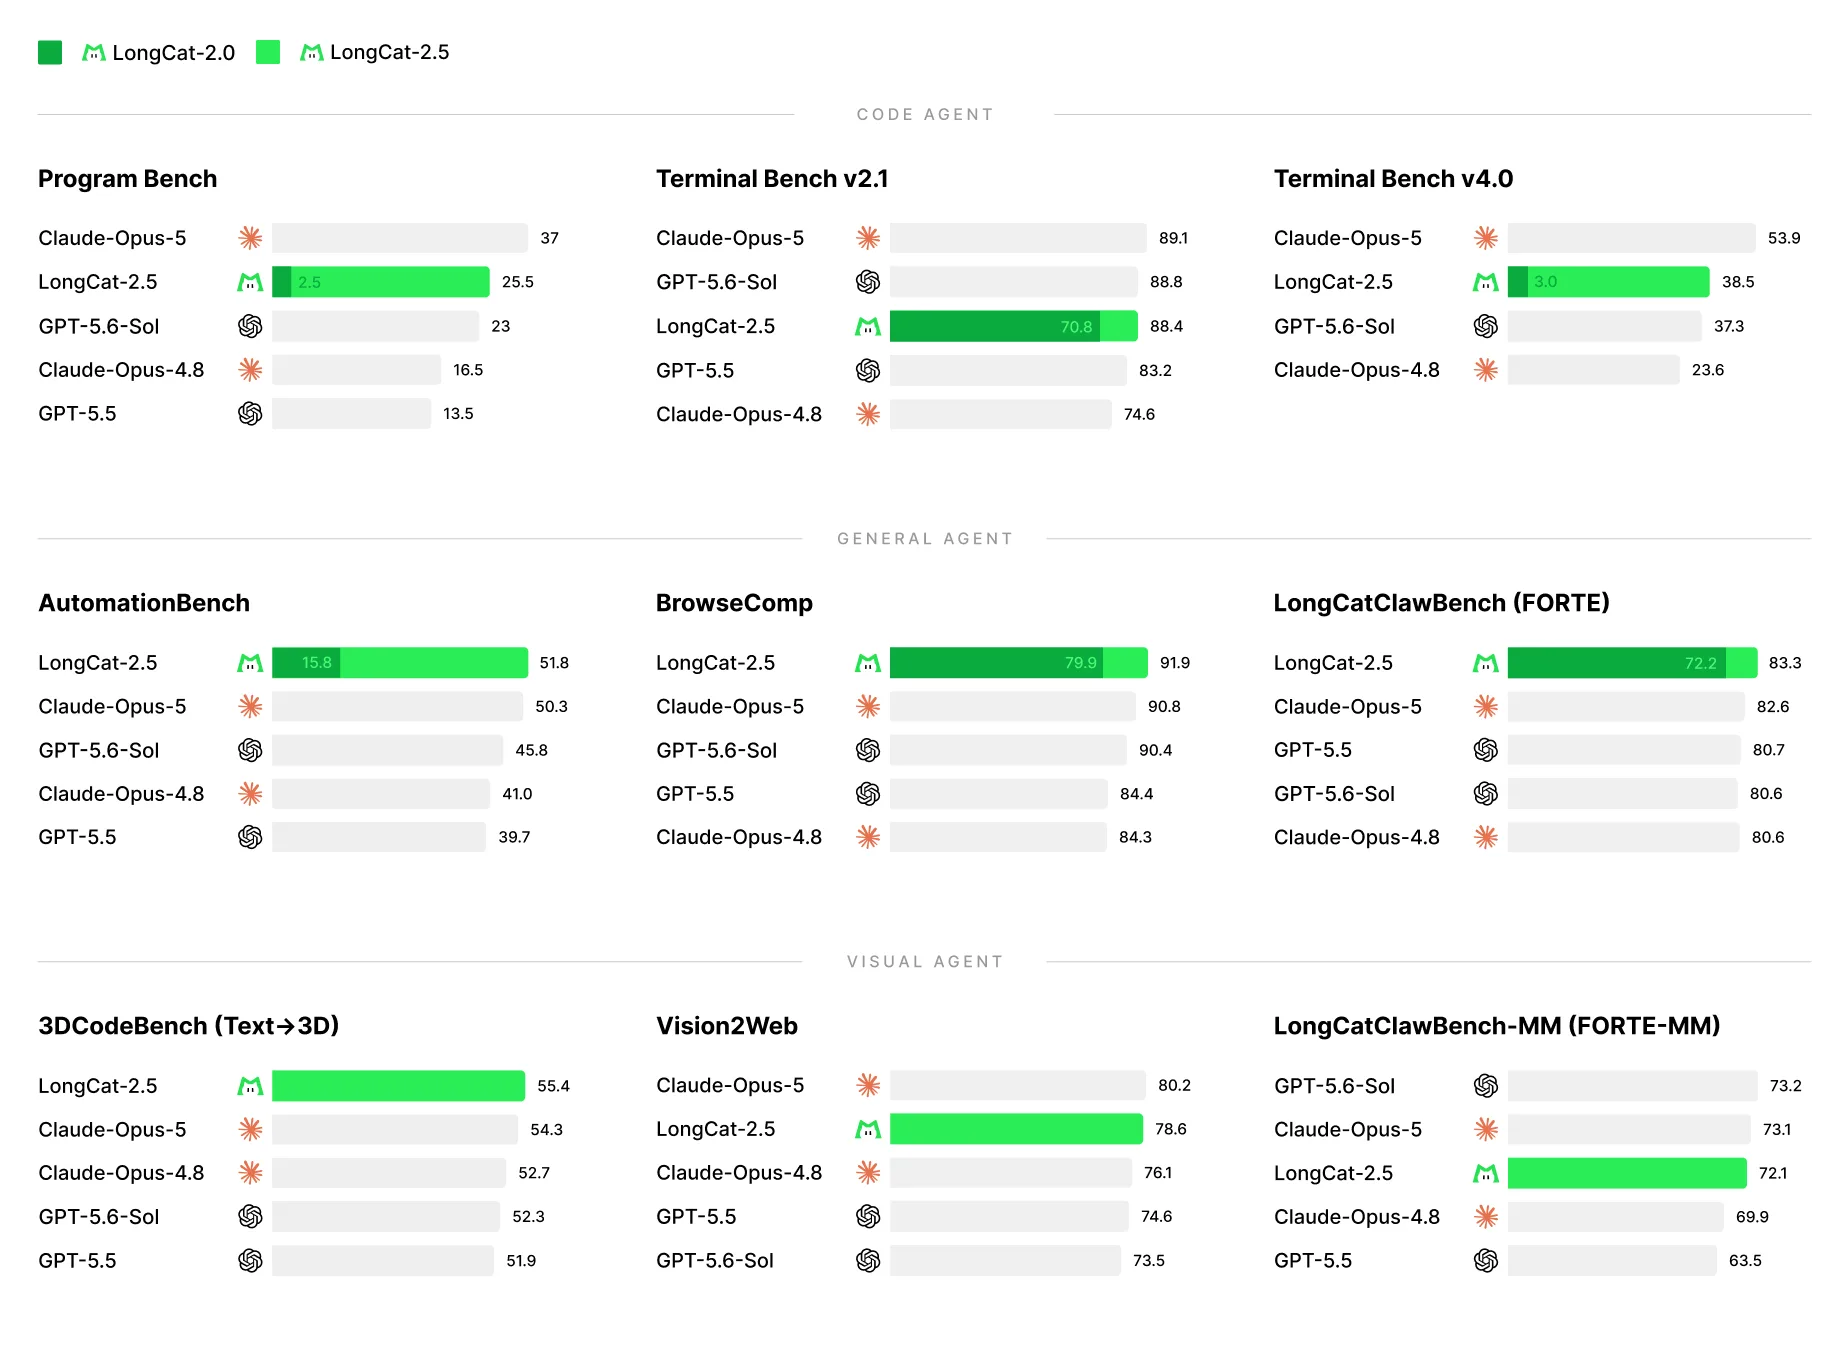
- 31 vendor-reported tests: Terminal-Bench 2.1 88.4, DeepSWE 64.6, BrowseComp 91.9 (table-best), 3DCodeBench 55.4 (table-best); independent score: none (Artificial Analysis has not rated it, as of Nov 13)
- Weights
- Released (2026-11-04, MIT license; full release 3,317.3 GB, W4A4 quantized build 1,244.3 GB; Hugging Face, plus a ModelScope mirror)
- Access
- longcat.ai/chat, LongCat API Platform (model ID
LongCat-2.5), Vercel AI Gateway, AnyRouter, OpenCode (free Zen tier), Nous Portal; not on OpenRouter (checked Nov 13) - Predecessor
- LongCat 2.0 (GA 2026-06-30, MIT weights); 2.5 shares 2.0's base model, adding vision and agent training
- Knowledge cutoff
- Not published by Meituan
02Timeline
Four months from 2.0 to 2.5: preview, announcement, GA and open weights inside seven weeks — the weights landed without even a formal announcement.
- 2026-04-20
LongCat 2.0 preview launches: a text-only agent model with 1M context.
- 2026-06-30
2.0 goes GA with MIT weights (Hugging Face repo created Jul 5); list price at the time $0.75 / $0.015 / $2.95.
- 2026-09-25
LongCat 2.5 preview launches: text-only, vision not yet enabled; a community self-test of the preview scored about 48.7% on Terminal-Bench 2.1 (single developer, different harness — reference only).
- 2026-11-01
Tech blog announces LongCat 2.5: 1.6T parameters, native multimodal architecture and 31 official benchmarks; weights marked "coming soon."
- 2026-11-02
GA on the LongCat API Platform: video understanding added at GA; the $0.30/$1.20 limited-time price takes effect the same day. Meituan's tech team blog publishes the training method (domestic accelerators, W4A4, long-horizon RL) the same day.
- 2026-11-04
Weights quietly land on Hugging Face: full + W4A4 repos, MIT license, no formal announcement; Nous Portal launches a free endpoint the same day.
- 2026-11-09
OpenCode Zen launches a free tier,
longcat-2.5-free; the paid version ships with OpenCode Go. - 2026-11-13
Artificial Analysis still hasn't rated it (ArtificialWatch's report that day: "not rated yet"); this topic page goes live.
03Official specs
As published by Meituan (tech blog, API Platform documentation and the Hugging Face weights repo's config.json, checked Nov 13, 2026). Note: max output and context each have two figures — see the text and section 09.
- Status
- Released (GA 2026-11-02); weights released (2026-11-04)
- Model ID
- LongCat-2.5
- Architecture
- Sparse MoE; 1.6T total parameters, about 48B active; 38 layers, 768 routed experts, top-12 routing, MLA attention, 163,840-token vocabulary
- Context window
- 1M tokens (API figure 1,048,576, input + output combined; config base 524,288, extended via YaRN rope scaling)
- Max output
- 128K tokens (Quick Start, FAQ and Meituan's Claude Code config; the Model Parameters page says max_tokens can reach 262,144 — the docs disagree, so plan on 128K)
- Input
- Text, image (PNG/JPG/JPEG/WebP/GIF, ≤10MB, ≤50 per request), video (≤100MB, <3600s, ≤10 per request, public URL only; no SVG/HEIC; aspect ratio >200:1 errors)
- Output
- Text
- Reasoning
- Returned via a reasoning_content field; temperature fixed (1.0 with thinking on, 0.7 with it off)
- API protocols
- OpenAI Chat Completions, OpenAI Responses (for Codex, effort none to xhigh), Anthropic Messages; endpoint api.longcat.chat
- Training
- Trained on domestic accelerators (<80GB VRAM); W4A4 quantized inference; long-horizon RL (F2P/P2P, anti-reward-hacking); MOPD multi-teacher distillation
- Benchmarks
- 31 vendor-reported tests (see section 06C); no independent score
- Weights
- MIT; full release 3,317.3 GB (210 shards), W4A4 1,244.3 GB (208 shards)
- License
- MIT
- API price
- $0.30 in / $0.006 cached / $1.20 out (limited-time discount, no end date)
04How to try it: six routes
The weights are open, but a 3.3 TB download and NPU-oriented deployment docs mean most people will still use a hosted API. Fastest free starts: OpenCode's free tier and the Nous Portal endpoint.
1LongCat API Platform (official main route)
Meituan's official API platform, model ID LongCat-2.5. OpenAI- and Anthropic-compatible, endpoint api.longcat.chat; prepaid balance never expires, only HTTP 200 requests are billed. Email signup, no identity check outside mainland China; the USD site takes credit cards, debit cards and Google Pay. Thirteen official tool setup guides (Claude Code, Codex, OpenCode, Cline, Kilo Code, Hermes, OpenClaw and more).
2longcat.ai/chat (official chat app)
The official chat entry point — sign in and use it; replies default to Mandarin. Some community feedback notes the login redirects to another domain, which feels disjointed.
3Gateways: Vercel AI Gateway, AnyRouter
2.5 is live on Vercel AI Gateway and AnyRouter, useful for developers who already bill through a gateway. Note: not on OpenRouter (checked via the OpenRouter API Nov 13 — only meituan/longcat-2.0 is listed); APIYI has announced plans to add it but had not as of Nov 3.
4OpenCode Zen free tier
Since Nov 9, OpenCode Zen offers a free tier, longcat-2.5-free; the paid version ships with OpenCode Go. A zero-cost trial for coding-agent work.
5Nous Portal free endpoint
A free endpoint went live Nov 4 — another zero-cost trial route.
6Self-hosting (weights are open)
Both Hugging Face repos are downloadable: the full release at 3,317.3 GB (210 shards) and W4A4 at 1,244.3 GB (208 shards), MIT license, with a ModelScope mirror. The README only documents NPU deployment via Meituan's SGLang-FluentLLM fork; vLLM support has no official statement (unverified), and Meituan publishes no VRAM guidance — don't estimate GPU counts from the 3.3 TB size.
05Pricing
The promo price matches DeepSeek V4.1 Flash's peak price to the cent — a deliberate head-to-head. But the discount has no end date and no list price, so long-term budgets can't be locked in at this rate. Prices checked Nov 13, 2026; the checkout page is authoritative.
| Item (per 1M tokens) | Promo price | RMB price |
|---|---|---|
| Input (uncached) | $0.30 | ¥2 |
| Cached input | $0.006 | ¥0.04 |
| Output | $1.20 | ¥8 |
| Volume discounts (verified companies, monthly spend $75+ / $300+ / $1,200+ / $6,000+) | 10% / 20% / 30% / 40% off | — |
| Token Packs (30-day quota, flash drops at 10:00 / 16:00 / 21:00 / 23:00 Beijing) | Sizes and prices behind login | — |
The cache price is the real weapon
Cached input at $0.006 is just 2% of the uncached rate (1/50) — a big deal for agent tasks that repeatedly read the same repo or long document. Meituan's worked example: 600K uncached input + 400K cached input + 500K output = $0.7824. Billing is friendly too: only HTTP 200 requests are charged, prepaid balance never expires, and there is no context-length surcharge and no image/video surcharge.
Same-price comparison
DeepSeek V4.1 Flash's peak price of $0.30/$1.20 is identical to LongCat's promo price, but DeepSeek halves its rates off-peak ($0.15/$0.60), making its monthly bill cheaper; same-tier flagships cost several times more: Kimi K3.1 Pro $2/$10 and Qwen3.8 Max $2/$6 (both official API prices, checked Nov 13).
Official pages: Meituan official tech blog · Hugging Face weights repo · LongCat official site
06Hands-on reviews
Everything below is a first read or hands-on from Nov 1–13: small samples, mixed methods — treat each as a case study. Watch the date trap: anything written before Nov 4 says the weights are "coming soon," which is now outdated. Each entry carries a verdict badge; "Read the local article" opens this site's rewritten deep dive, with the original source at the end.
Chinese sources
Meituan tech team blog: how the long-horizon agent was trained
Verdict: the only detailed disclosure of the training methodSource: Meituan tech team blog, 2026-11-02 (training: long-horizon RL, MOPD distillation, W4A4 quantization)
Long-horizon reinforcement learning uses an F2P/P2P framework with anti-reward-hacking design; multi-teacher distillation (MOPD) compresses several teachers into one model; W4A4 quantized inference is about 43% faster on both prefill and decode, with time to first token down about 16%. Training ran entirely on domestic accelerators, each with under 80GB of VRAM.
Beijing News: a trillion parameters, trained on domestic accelerators
Verdict: Chinese press coverage of the training infrastructureSource: Beijing News (translated by TokenHeart), 2026-11-02
The report focuses on the 1.6T parameter scale and the all-domestic-accelerator training run; it adds no benchmark methodology or pricing detail beyond the official blog.
English sources
eesel deep dive: a cheap vision coding agent, but same-price DeepSeek is stronger
Verdict: worth trying, but don't expect it to beat DeepSeekSource: eesel, 2026-11-03 (page-by-page read of the official docs: vision limits, output cap, community feedback, data policy)
Vision input is 2.5's real increment, but the output cap is disputed — 128K vs 262,144 — and eesel advises planning on 128K; Reddit reports looping on long tasks and degradation past about 200K context; the FAQ says nothing about prompt retention or training use, a red flag for support use cases. Note: eesel wrote on Nov 3, so its "weights unreleased" conclusion is outdated since the Nov 4 MIT release.
Read the local article → (our own write-up)
apiyi benchmark guide: 25 tests, item by item
Verdict: the fullest reading of the official table, with pricing math and setup stepsSource: apiyi, 2026-11-03 (official benchmark table, pricing examples, setup guide)
Item-by-item coverage of the official benchmark table with a full breakdown of the $0.7824 worked example; a companion piece explains the long-horizon agent training. Also written before the weights release, so its "weights coming soon" wording is outdated.
Read the local article → (our own write-up)
ToolPilotPro three-way comparison: careful bill math, half-outdated conclusions
Verdict: the bill math is solid; use our corrected version for the openness verdictSource: ToolPilotPro, updated 2026-11-04 (LongCat vs Kimi vs DeepSeek)
Monthly workload math (40M input, half cached, + 8M output): DeepSeek $7.86 off-peak / $15.72 peak, LongCat $15.72, Kimi $124. But the Nov 4 update still calls LongCat API-only with weights "coming soon" — the MIT weights have been on Hugging Face since Nov 4, and our comparison is corrected accordingly.
Read the local article → (our own write-up)
OrcaRouter preview analysis: a preview-era check
Verdict: preview data — reference only after GASource: OrcaRouter, data from 2026-10-13 (preview verification)
An early check of the preview's specs and pricing; vision, video input and the weights status have all changed since GA, so post-GA sources take precedence.
TokenDyno live speed test: about 51.8 tok/s
Verdict: mid-pack speed, tiny sampleSource: TokenDyno, 2026-11-13 (OpenCode Go, n=4)
LongCat 2.5 (Free) on OpenCode Go runs about 51.8 tok/s with a time to first token of about 2.8 seconds. Only four samples, and gateway and load affect results — reference only.
Community feedback: looping, the comparison set, and one self-test
Verdict: anecdotes, but they all point at the same gap — no independent reproductionSource: Reddit, Hacker News, from 2026-11-02
Reddit preview feedback: loops on long tasks, good in narrow roles on small tasks, not suited to planning or creative writing; HN criticized the price and the comparison set (the headline chart omits Opus 5.5, GPT-6.1 Sol and Kimi K3.1 Pro); a single developer self-tested the preview at about 48.7% on Terminal-Bench 2.1 — a different harness and version from the official 88.4, so not directly comparable.
06BArticles: our in-depth coverage
The six articles below are our own rewritten and reorganized deep dives — restructured, with added conclusions and selection advice, and facts and figures checked against the original reviews. Open any one to read it on this site; the original source is linked at the end.
06CBenchmarks: 31 official tests, no independent measurement (yet)
Meituan published 31 tests in three groups — code agent, general agent, visual — and the data is thorough; but all of it is vendor-run, and rival scores are half public reports, half Meituan's own runs. Read the conditions first, then the independent measurements — currently, there are none.
| Test (official table, vendor-run) | 2.5 | 2.0 | Same-price rival: DeepSeek V4.1 Flash |
|---|---|---|---|
| Terminal-Bench 2.1 | 88.4 | 70.8 | 90.6 |
| Terminal-Bench 4.0 | 38.5 | 3.0 | 31.2 |
| DeepSWE v1.1 | 64.6 | 9.7 | 74.2 |
| BrowseComp | 91.9 | — | 91.5 |
| 3DCodeBench Text→3D | 55.4 | — | — |
| PaperBench | 82.1 | — | — |
| VideoMME | 85.2 | — | — |
| HLE (with tools) | 63.1 | — | — |
| JobBench | 65.4 | — | — |
| MCP Atlas | 83.1 | — | 84.4 |
| AutomationBench | 51.8 | 15.8 | 54.8 |
| NL2Repo | 60.5 | — | 65.4 |
| ProgramBench | 25.5 | 2.5 | 20.3 |
| Agents' Last Exam v1.1 | 38.5 | — | — |
| ResearchRubrics | 81.0 | — | — |
Independent measurement and third-party data
| Measurement | Source | 2.5 result | Notes |
|---|---|---|---|
| AA Intelligence Index | Artificial Analysis | Not rated (as of Nov 13) | The AA list has only 2.0 and Flash Lite |
| ArtificialWatch report | ArtificialWatch, Nov 13, 08:59 UTC | "not rated yet" | — |
| TokenDyno live speed test | TokenDyno (OpenCode Go, n=4) | About 51.8 tok/s, TTFT about 2.8s | — |
| OpenVibeEval ranking | OpenVibeEval leaderboard | 2.5 Preview ranked No. 40 | Preview, not the GA release |
| Community self-test, TB 2.1 | Single developer, preview, different harness | About 48.7% pass@1 | Not comparable to the official 88.4 |
Full coverage in our benchmarks article →
07Comparisons
vs LongCat 2.0 (predecessor)
| Dimension | LongCat 2.5 | LongCat 2.0 |
|---|---|---|
| Released | GA 2026-11-02 | GA 2026-06-30 |
| Parameters | 1.6T total / about 48B active | Same base model (2.5 shares 2.0's base) |
| Input | Text, image, video | Text only |
| Weights | MIT, released (Nov 4) | MIT, released |
| Terminal-Bench 2.1 | 88.4 | 70.8 (AA measured 50.2) |
| Terminal-Bench 4.0 | 38.5 | 3.0 |
| DeepSWE v1.1 | 64.6 | 9.7 |
| AutomationBench | 51.8 | 15.8 |
| ProgramBench | 25.5 | 2.5 |
| Price | $0.30 / $1.20 (promo) | $0.75 / $2.95 (old list price) |
The 2.5 jump comes from vision and agent training, not scale — same base model, yet Terminal-Bench 4.0 went from 3.0 to 38.5 and DeepSWE from 9.7 to 64.6. And the price went down: the promo rate is about 40% of 2.0's old list price.
vs same-price and same-tier rivals (as of 2026-11-13)
| Model | Released | AA Index | API price $/1M (in / out) | Weights |
|---|---|---|---|---|
| Meituan LongCat 2.5 | Nov 2 | Not rated | 0.30 / 1.20 (promo) | MIT, released |
| DeepSeek V4.1 Flash | Sep 10 | 32.6 | 0.30 / 1.20 (peak); 0.15 / 0.60 (off-peak) | MIT, released |
| Kimi K3.1 Pro | Oct 23 | 46 | 2.00 / 10.00 | Released Nov 4 (custom license) |
| Tencent Hy4 | Nov 4 | 35 | 0.83 / 2.50 (50% off: 0.42 / 1.25) | Pending |
| Inkling 2 Small | Nov 5 | 31 | 0.30 / 1.00 | Apache 2.0, released |
08What's missing (as of Nov 13)
- An Artificial Analysis score (not rated as of Nov 13; no third-party benchmark reproduction exists)
- A data policy: whether prompts are retained or used for training, unaddressed in the FAQ
- The promo discount's end date and the post-discount list price
- Token Pack sizes and prices (behind login, unpublished)
- Rate limits (RPM/TPM, unpublished)
- vLLM support and self-hosting VRAM guidance (the README only covers NPU + SGLang-FluentLLM)
- Knowledge cutoff date (not published)
- A dated retirement notice for 2.0 / 2.5-Preview (gone from the model list, no formal notice)
- Independent long-context evaluation of the 1M window (config base 512K + YaRN, unverified in practice)
- Reconciliation of the 128K vs 262,144 max-output figures in the docs
09Rumor check
Most LongCat 2.5 confusion comes from timing — coverage from Nov 1–3 was largely outdated by the Nov 4 weights release — plus a few misreported numbers, clarified item by item below.
False "440B active parameters"
Some launch-day community posts claimed 440B active — wrong. The official figure is about 48B active (config.json: 768 routed experts, top-12 routing); 440B has no official source.
Clarified "Weights coming soon — API only"
Every report from Nov 1–3 said this (including ToolPilotPro's comparison, updated Nov 4), but both repos have been on Hugging Face since Nov 4: the full release at 3,317.3 GB and W4A4 at 1,244.3 GB, MIT license. This site verified the creation times and licenses via the HF API.
False "$0.30/$1.20 is the permanent price"
The official pricing page labels it a limited-time discount, with no end date and no list price, adding "prices may change." 2.0's old list price was $0.75/$2.95 — if 2.5 moves there, output would cost about 2.5× more (speculation; Meituan has not said so).
Partly true "Terminal-Bench 2.1 is only 48.7%"
48.7% is a single developer's self-test of the preview on a different harness — not the GA release's score; the official 88.4 is likewise a vendor figure. The two numbers don't measure the same thing, and neither is a verdict on the GA release until an independent reproduction exists.
Partly true "1M context"
The API figure is indeed 1,048,576 (input + output combined), but the config base is 524,288, extended to 1M via YaRN. 2.0 had a history of "1M advertised, 256K in the config" (eesel), and 2.5's 1M has no independent long-context evaluation yet.
Clarified "Was it released Nov 1 or Nov 2?"
The tech blog announced it Nov 1; the API Platform went GA Nov 2. This site uses Nov 2 as the release date: the first day it was actually usable. The preview was Sep 25.
10FAQ
When was LongCat 2.5 released?
Announced on the tech blog Nov 1, 2026, and GA on the LongCat API Platform Nov 2; the preview shipped Sep 25. This site uses Nov 2 as the release date. See the timeline in section 02.
Where can I download the LongCat 2.5 weights?
From two repos under the meituan-longcat organization on Hugging Face: LongCat-2.5 (full release, 3,317.3 GB, 210 shards) and LongCat-2.5-W4A4 (1,244.3 GB, 208 shards), both MIT-licensed, published Nov 4, 2026; ModelScope also mirrors them. See our weights status article.
Is LongCat 2.5 open source?
Yes. The weights were released Nov 4, 2026 under the MIT license — commercial use, modification and redistribution are all allowed; 2.0 is MIT too. Note that much early-November coverage still says the weights are "coming soon" — that's outdated.
How much does LongCat 2.5 cost?
Promo pricing: $0.30 input / $0.006 cached input / $1.20 output per 1M tokens (¥2 / ¥0.04 / ¥8). The discount has no end date and no list price, and Meituan says "prices may change." Only HTTP 200 requests are billed; prepaid balance never expires. See our pricing guide.
How do I use LongCat 2.5, and where is it available?
The official chat app at longcat.ai/chat, the LongCat API Platform (model ID LongCat-2.5), Vercel AI Gateway and AnyRouter; free routes include OpenCode Zen (longcat-2.5-free) and the Nous Portal free endpoint. Note: it's not on OpenRouter. Self-hosting is possible with the MIT weights, but the README only documents NPU + SGLang-FluentLLM.
What is LongCat 2.5's AA Index score?
As of Nov 13, Artificial Analysis has not rated LongCat 2.5 — there is no independent score; the AA list has only 2.0 and Flash Lite. ArtificialWatch's Nov 13 report likewise says "not rated yet." This site will keep tracking it.
Can I trust the 88.4 on Terminal-Bench 2.1?
88.4 is Meituan's self-reported figure (Claude Code v2.1.280 harness, max sequence 512K) — treat it as a vendor figure until an independent reproduction exists. Warning: AA once measured 2.0's TB 2.1 at 50.2%, 20 points below Meituan's table figure of 70.8; a community self-test of the 2.5 preview scored about 48.7% on a different harness (reference only).
How does LongCat 2.5 differ from 2.0?
They share a base model; 2.5 adds native vision (image + video input) and long-horizon agent training: Terminal-Bench 4.0 rose from 3.0 to 38.5, DeepSWE from 9.7 to 64.6, AutomationBench from 15.8 to 51.8. The price went down instead: the 2.5 promo of $0.30/$1.20 is about 40% of 2.0's old list price of $0.75/$2.95.
How does LongCat 2.5 compare with DeepSeek V4.1 Flash?
The promo/peak prices are identical ($0.30/$1.20), but DeepSeek halves its rates off-peak, so its monthly bill is cheaper; on benchmarks DeepSeek leads most coding rows (DeepSWE 74.2 vs 64.6, TB 2.1 90.6 vs 88.4), while LongCat leads TB 4.0 (38.5 vs 31.2), BrowseComp (91.9 vs 91.5) and ProgramBench (25.5 vs 20.3). Both weights are MIT. See our three-way comparison.
Does LongCat 2.5 support vision and video?
Yes. Input can include images (PNG/JPG/JPEG/WebP/GIF, ≤10MB, ≤50 per request) and video (≤100MB, <3600s, ≤10 per request, public URL only); SVG/HEIC are not supported, and an aspect ratio >200:1 errors. Vision uses native multi-level discrete tokens with no separate vision encoder; output is still text-only. Video understanding arrived with the Nov 2 GA — the preview didn't have it.
Is max output 128K or 262K?
The official docs disagree: the Quick Start, FAQ and Meituan's Claude Code config say 131,072 (128K), while the Model Parameters page says max_tokens can reach 262,144. This site's advice, matching eesel's: plan on 128K; 262K is unverified.
How large is LongCat 2.5's context window?
The API figure is 1,048,576 tokens (input + output combined). The weights repo's config base is 524,288, extended to 1M via YaRN rope scaling; real-world long-context performance has no independent evaluation yet.
11Sources
Every fact on this page comes from the public sources below (checked Nov 13, 2026).
Official
- Meituan LongCat team — Introducing LongCat-2.5 (official tech blog, with the 31-test benchmark table and architecture details) Nov 1
- Meituan tech team — Meituan LongCat 2.5: long-horizon agent training (long-horizon RL, MOPD distillation, W4A4 quantization, Chinese) Nov 2
- Hugging Face — meituan-longcat/LongCat-2.5 (MIT weights, full release 3,317.3 GB, with config.json and the benchmark table) Nov 4
- Hugging Face — meituan-longcat/LongCat-2.5-W4A4 (W4A4 quantized weights, 1,244.3 GB) Nov 4
- LongCat official site — longcat.ai (chat app and API Platform entry)
English coverage and analysis
- eesel — LongCat 2.5: Meituan's New Multimodal Coding Model, Explained (page-by-page read of the official docs) Nov 3
- apiyi — What Can LongCat 2.5 Actually Do? (official benchmarks and pricing guide) Nov 3
- apiyi — LongCat 2.5 Long-Horizon Agent Training, Explained
- ToolPilotPro — LongCat-2.5 Guide (pricing and discount details)
- ToolPilotPro — LongCat-2.5 vs Kimi K3.1 Pro vs DeepSeek (three-way comparison; the Nov 4 update still says API-only — outdated) Updated Nov 4
- OrcaRouter — LongCat 2.5 preview analysis (data from Oct 13)
- ArtificialWatch — LongCat 2.5 report ("not rated yet") Nov 13
- TokenDyno — live speed test (OpenCode Go, about 51.8 tok/s, n=4)
- OpenVibeEval — leaderboard (2.5 Preview ranked No. 40)
- TokenHeart — Beijing News report in English: trillion parameters, trained entirely on domestic accelerators